Artificial intelligence is increasingly being used to produce summaries and reports of complex content. The advantage is obvious. In just a few seconds you can obtain a summary of information that would take much longer to examine. But what if the result contains a wrong detail?
This is the question from which a study conducted by Georgetown University and the University of Washington starts. The authors analyzed not only the errors produced by the models, but also the possible effect that misleading information can have on human memory. The point, therefore, is not only to understand how reliable the result produced is, but also whether any inaccuracies could affect those who read it.
How the study on AI-generated summaries was conducted
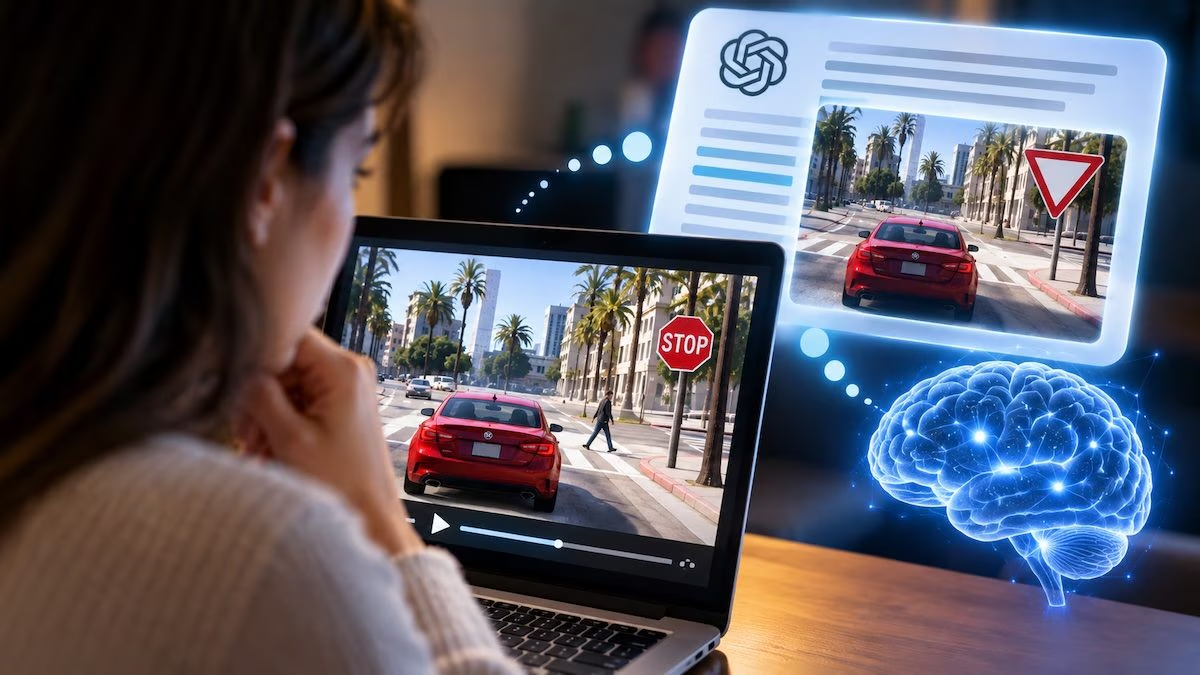
The study followed two steps. In the first, the researchers put ChatGPT-5.5 and Gemini 2.5 Flash-Lite to the test, entrusting the two models with the task of summarizing two short animated videos, both lasting 25 seconds. The scenes, created within Grand Theft Auto V and already used in previous memory studies, showed a red car reaching an intersection, turning and hitting a pedestrian.
The videos were nearly identical, but had one central difference. In one there was a STOP sign, in the other a give way sign. Each model received each video five times, always in a new session, producing a total of 20 summaries.
The prompt, i.e. the instruction provided to the models, was formulated precisely to reduce the risk of inaccuracies. Systems were asked to produce at least 300 words, maintain a neutral and factual tone, introduce no new interpretations or elements, and include all important events. Despite these indications, all 20 texts contained errors, ranging from a minimum of 7 to a maximum of 21 per text.
Omissions were the most frequent category. The researchers had identified 19 central details of the scenes and, on average, the models missed 51.6% of them. Even more surprising is that 19 out of 20 texts did not mention the main event, i.e. the car hitting the pedestrian, a figure corresponding to 95%. In other cases, inaccurate information appeared, additions not present in the video or actual “hallucinations” of the AI, such as vehicles or people that did not exist in the original sequence.
This first analysis served above all to identify which problems could emerge. To test whether these inaccuracies also had consequences on readers, the authors therefore organized a second experiment.
One wrong detail can change our memories
US adults recruited online participated in the second experiment. 331 completed both sessions and, after exclusion of three individuals who failed an attention check, 328 participants were included in the analyses. Everyone watched one of the two videos and had to pay attention to what was happening. After 24-48 hours he returned for the next phase and read a 21-sentence summary generated with ChatGPT.
The decisive step concerned the road sign. Depending on the group, the text correctly reported the one seen in the film or replaced it with the other one. Anyone who had observed a STOP could therefore read that the car had arrived at a yield signal and vice versa. The rest of the synthesis remained substantially the same, so as to isolate the effect of that single detail.
Immediately afterwards, volunteers were asked to answer a series of questions based on the original video, not the text they had just read. Among these, one asked what signal was present at the intersection.
The difference was clear. Among those who had read a summary consistent with the video, 83.6% remembered the correct sign. In the group exposed to misleading information, however, the percentage dropped to 44.8%. The other questions indicate that the volunteers had not simply forgotten the whole scene. For example, 96.6% recalled that the accident occurred during the day and, on average, participants gave the right answer to 91.4% of the 11 non-core questions.
Then there is another interesting element. Before reading, some participants were told that the summary was produced by an AI system, others that it came from a human transcriber. In reality the content was always generated with ChatGPT. Knowing, or believing, that artificial intelligence was behind the text did not significantly reduce the effect of misinformation. Not even the reported level of trust in AI systems or the frequency with which they were used seemed to impact the outcome.
Why misleading information can interfere with memory and what are the limits of research
The phenomenon did not arise with artificial intelligence. In psychology it has been known for decades as misinformation effect. After experiencing or observing an event, subsequent exposure to inaccurate information can change how certain details are remembered. Memory, in fact, does not function as an immutable record, but is the result of a reconstructive process, also influenced by what we learn later.
The research applies this mechanism to texts produced by generative models. The most delicate point is that the error does not necessarily have to be glaring. A seemingly small detail, such as a STOP transformed into giving way, can be enough to interfere with memory. And this is precisely what makes the topic relevant when automatic syntheses are used in contexts where accuracy matters a lot.
The authors cite, for example, the use of AI to generate police reports or summaries. In these cases we often tend to think that the presence of a person responsible for verifying the generated text, the so-called human in the loopcan correct any errors. However, the study suggests a possible problem. The same person called to check the text could be influenced by the inaccurate information he is reading.
This does not mean, however, that every AI summary has been shown to impair memory or that the same results automatically occur in real-world situations. The experiment was very controlled, involved two simple animated videos and directly tested the effect of only one type of false information, namely the road sign. The error analysis of the models was also limited to a single prompt and 20 generated texts.
The result highlights a concrete risk: an error in an automatic synthesis can affect the way in which a person reconstructs what he had seen. The same authors underline, however, the need to verify the phenomenon with more realistic materials and in different scenarios.